4 Success Factors for Machine Learning in Fraud Detection
Machine learning in fraud detection performs better when we know the strengths and limitations of different analytic toolkits, and understand the factors that determine accuracy.

In a recent blog post, I discussed how FICO is fighting application fraud by leveraging artificial intelligence (AI) and machine learning in fraud detection, including an overview of supervised, unsupervised, and adaptive analytics techniques and the need to balance transparency (explainable AI) with predictiveness.
Most computer software encodes a set of rules — an algorithm — that a human has explicitly defined. Machine learning enable us to build predictive software that “learns” from data instead of being told explicitly what to do. Hence, machine learning in fraud detection provides tremendous value above and beyond the broad-based approach of rules-only based detection, including considerable performance lift.
Contrary to popular belief and our deepest wishes, however, you can’t just throw a bunch of data at a machine learning model and expect success. Machine learning in fraud detection performs better when we know the strengths and limitations of myriad of analytic toolkits (e.g., supervised vs. unsupervised approaches), and understand the factors that determine accuracy. Let's dig into the four categories of factors.
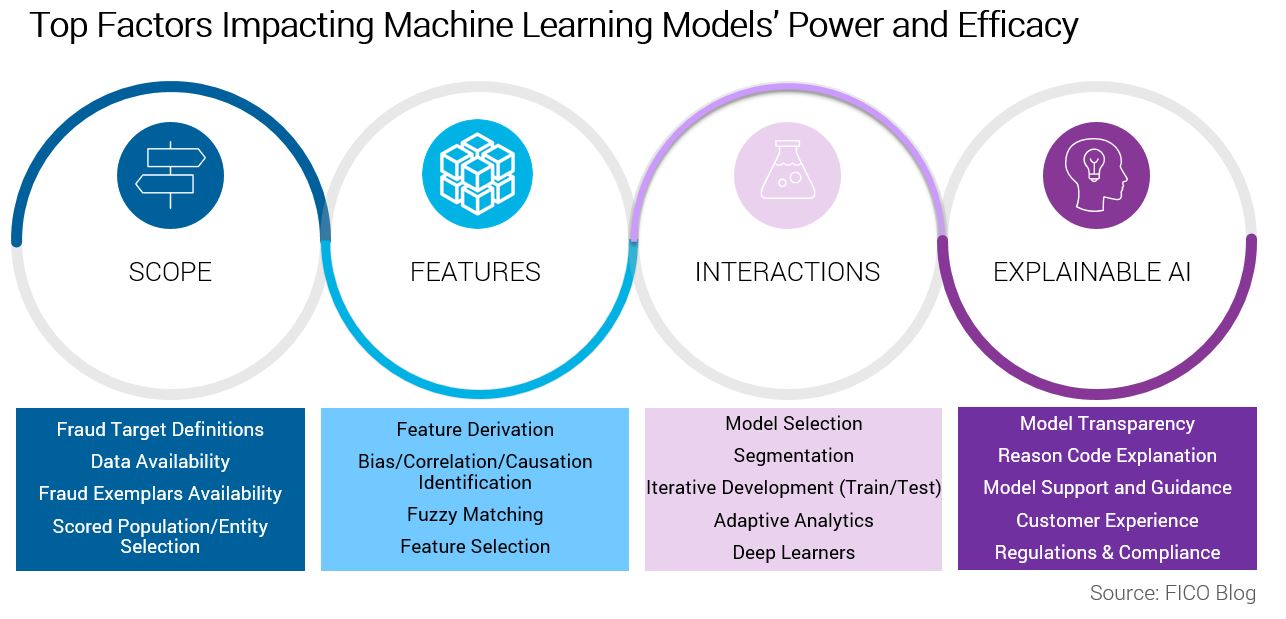
Scope
Scope requires setting a reasonable objective for a model, including identifying the target you want to make a prediction about and ensuring there is sufficient data. While a highly focused model only addresses a small, specialized part of a fraud problem, we are able to optimize and refine the model to do that specific job very well. On the other hand, a general model can address a larger class of a fraud types, with the trade-off that it may not perform as well as a specialized model. Often the best is a combination of focused and general scored models that can be efficiently handled by segmentation via sub-models.To strike the right balance, we must ask:
- What entity are we scoring — the application, the applicant, the customer, the account?
- What models are built for specific fraud schemes (e.g., synthetic identities, bust-outs) or is the fraud definition more generic (e.g., third-party and first-party fraud) requiring broader defined fraud detection models?
- What historical data is required to support the development of the model types — are there sufficient fraud tags?
- Is the model consortium utilizing various clients’ definitions of fraud types that must be fused to take advantage of broader insight and performance gained from consortium approaches?
- How long is the model expected to be used in production? What is the anticipated lifetime of the mode? Do we need adaptive and self-learning technologies to keep the model robust?
- What are the transparency requirements of the model?
Features
Machine learning models rely on features derived from the historical data to infer the patterns and relationships within the data. In other words, data doesn’t cut it and we need to create feature detectors of both fraud and non-fraud supported both by the available historical data and the anticipated production data. We need to appropriately define features based on the current historical fraud and non-fraud behaviors, and create features that are generic and that will adapt to new patterns in the production data as fraudsters change their tactics.There are many types of features that FICO uses in our own application fraud model characteristic libraries. One example is the use of Network Analytics (SNA), as was discussed in a recent FICO webinar, Layered Defenses in the Fight Against Application Fraud. Other examples include behavioral profiling techniques, archetypes clustering, bureau characteristics, output of fuzzy matching, and many more that are a topic for another day.
Interactions
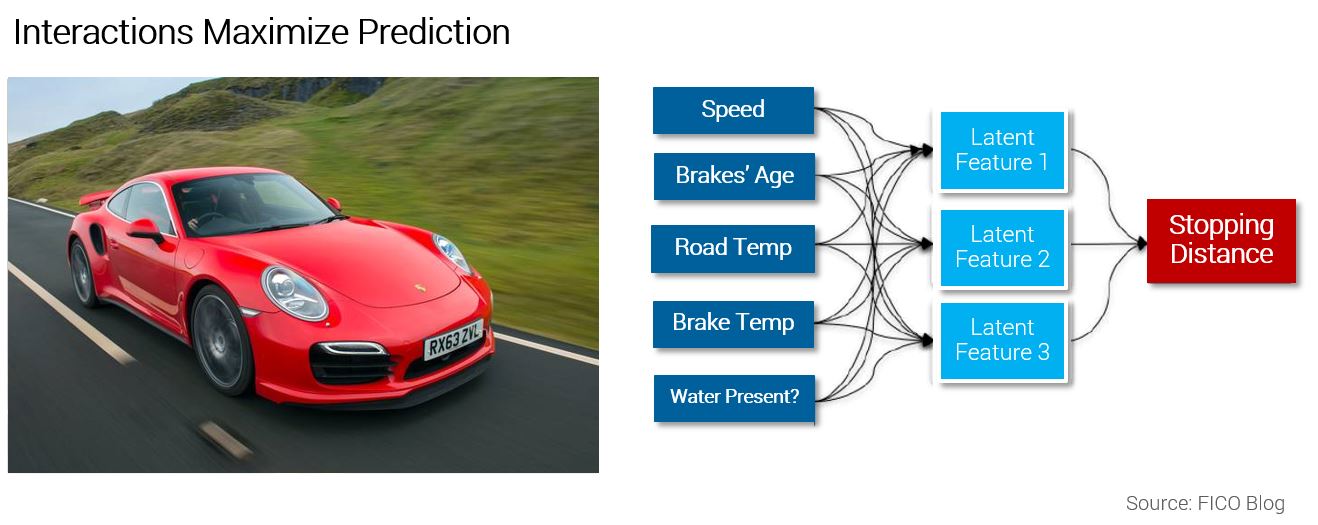
From feature creation we have a number of feature detectors, each with varying degrees of predictive power, but they must be combined into a score. Machine learning allows the signals in data to be combined in optimal ways to maximize detection and minimize false positives. The relationships learned are far too complex for human analysts, or indeed the data scientist, to impute. The machine learning process facilitates learning of nonlinear combinations of features — latent features — where machine learning explores which combinations of features lead to interactions between signals that strengthen predictiveness.For example, consider the raw data inputs needed to determine the stopping distance of a car. You could capture a variety of data points such as ambient temperature, the presence of water, and weight of the vehicle. There are relationships between these inputs that are far more powerful than a simpler model that does not model interaction terms would learn from historical data.
However, to achieve the most accurate results, the model should also look at interactions between these variables. For example, the relationship between water and temperature indicates the presence of ice — clearly a predictive feature that strongly influences stopping distance.
Explainable AI
One of the biggest challenges in operationalizing machine learning in fraud detection is the need for transparency in a highly regulated credit lending environment. FICO is on the frontier of explainable AI (XAI), researching and developing techniques to enable humans to understand how the machine learning model reached its score, increase the shelf life of analytic models, and providing real-world applicability for organizations to utilize the power of advanced analytics while meeting governance and regulatory requirements on ML.Stay Tuned for More
Next up in my blog series is an interview with data scientist and application fraud domain expert Derek Dempsey. In the meanwhile, be sure to check out our previous posts on application fraud:Popular Posts

Average U.S. FICO® Score at 716, Indicating Improvement in Consumer Credit Behaviors Despite Pandemic
The FICO Score is a broad-based, independent standard measure of credit risk
Read more
The GSE Data Is Public. Here's What It Shows About Credit Score Modernization.
Independent Milliman analysis of GSE historical data confirms what anyone can now verify directly: FICO® Score 10T is the most predictive score.
Read more
FICO® Score High Achievers: Is Age the Only Factor?
<p>FICO’s latest research on <a href="http://www.fico.com/en/blogs/risk-compliance/us-credit-quality-rising-the-beat-goes-on/" target="_blank">national FICO® Score distribution</a> shows that US credit quality continues to trend upwards, with an increasing number of consumers scoring in the highest scores ranges. Given that, we decided it was time to refresh our study on “<a href="http://www.fico.com/en/blogs/risk-compliance/infographic-what-does-a-high-credit-scorer-look-like/" target="_blank">FICO® Score high achievers</a>,” where we examine the credit behavioural profiles of consumers with higher credit scores.</p> <p>As expected, our latest study showed that older people generally have higher scores, as has been the case in our <a href="http://www.fico.com/en/blogs/risk-compliance/age-before-beauty-credit-worthiness-before-youth/" target="_blank">past research</a>. This is largely because they have trade lines that have been open longer, which leads to higher scores (assuming the trade lines are in good standing and all other things equal). The most credit savvy among you will remember that length of credit history accounts for roughly 15% of the overall <a href="http://www.myfico.com/CreditEducation/WhatsInYourScore.aspx" target="_blank">FICO® Score calculation</a>.</p> <p>But for younger consumers, it isn’t too helpful to say, “just wait until you are 50 years old, and that will fix things!” Thus, I decided to dive deeper with our analysis, including looking at the credit behavioural characteristics of younger consumers with high FICO® Scores.</p> <p>In this analysis, I looked at credit characteristics for the two highest score bands, 750-799 and 800-850, which have about 16% and 23% of the population, respectively. I further broke this down by looking at the characteristics of the youngest 15% in each group, which occurs at age 29 for the 750-799 group and 43 for the 800-850. We used FICO<strong>®</strong> Score 9 for our analysis, and examined typical variables of the categories that go into the make-up of the score.</p> <p><a href="http://www.fico.com/en/blogs/wp-content/uploads/2016/10/FICO-Score-High-Achiever-table.png"><img class="alignnone size-full wp-image-29367" src="http://www.fico.com/en/blogs/wp-content/uploads/2016/10/FICO-Score-High-Achiever-table.png" alt="fico-score-high-achiever-table" width="715" height="747" /></a></p> <p>Since there’s a lot to dissect in this chart, I’ll highlight a few findings that struck me: <ul> <li><strong>Credit history.</strong> Higher scores are undoubtedly associated with a longer time on file. What’s striking is the higher average time on file for the 800+ group, both overall and for revolving accounts (the most common trade line). Clearly, it helps to start credit use early in life – but that’s not the sole determining factor for high scoring. The younger cohorts in both the 800+ and 750-799 groups have time on file medians significantly less than their older counterparts.</li> <li><strong>New credit.</strong> High credit scorers do, in fact, pursue new credit. We see little variation in months since last trade line opening and last inquiry among all groups observed.</li> <li><strong>Pay on time.</strong> As you might expect, the further in the past the delinquency, the higher the score – and that’s <u>if</u> a delinquency ever happened. 95% of the 800+ people and 72% of the 750-799 group have never been delinquent, which is a striking contrast to the 57% for the total population. The percentages for the younger groups are even higher, especially so for the 750-799ers. Collection items are also scarce for these high scorers. While 23% of the national population have collection items greater than $99, the figures are only 0.5% for the 800+ group and 3% for the 750-799 group. It is clear that, in conjunction with starting a credit file early, paying on time is a key trait of the FICO® Score high achiever.</li> <li><strong>Balance and utilization.</strong> Finally, we look at how credit is being used, focusing on revolving product use. (Since most people only have one mortgage or one auto loan, variation in instalment product figures is minimal and driven by payment history, which is near perfect for high scorers, as we’ve seen.) FICO® Score high achievers tend to have more open revolving accounts. While the % active trades and utilization are generally lower, by no means do high scorers avoid the use of credit products. What drives the difference here is the amount of <u>available</u> revolving credit utilized. The 800+ group is roughly 1/4 of the national median, both in total and on their highest utilized card; they also have lower balances and more cards<em>. </em>The 750-799 group is more active and higher utilized, but still only at 2/3 of the national figures. The young 750-799 group compensate with lower revolving balances and, as a result, lower utilization, which is in line with what we see for the 800+ group.</li> <li><strong>Benchmarks.</strong> I’d like to point out that while this study provides good benchmarks of the typical credit traits of the FICO® Score high achiever, individual credit profiles will vary widely. And keep in mind that when we sort groups of consumers as a whole by different behaviours, some results may look superficially odd. For example, the 800+ band has a longer median average open account time (128 months) than average revolving months on file (140 months).</li> </ul> So, what do we conclude? A huge takeaway is that high scorers don’t have too much in the way of serious delinquencies and negative public record data.</p> <p>In most respects, the young 800+ people are like their peer group. They really only differ markedly in their shorter credit history and higher non-mortgage balance, both of which are a function of life stage. Our results show that you don’t have to be a credit product hermit; these high scorers have more credit cards. The takeaway is to start credit activity early and maintain well-managed and moderate usage.</p> <p>In many ways, the young 750-799 people are more interesting because their age profile is much younger. Their credit characteristics differ more from their peer group, particularly in terms of length of credit history. They compensate by having almost pristine credit records and lower balances.</p> <p>Ultimately, 39% of US consumers are FICO® Score high achievers, which they accomplish by following common-sense credit practices. It ain’t rocket science!</p>
Read moreTake the next step
Connect with FICO for answers to all your product and solution questions. Interested in becoming a business partner? Contact us to learn more. We look forward to hearing from you.