Rank Distillation: Operationalizing AI Continuity in the Corpus AI
New models can underperform alarmingly easily if you take your eyes off the Corpus AI

Decision management systems are complex, consisting of numerous components such as machine learning (ML) models, decision strategies, rules systems, alert management and performance monitoring. Too often, machine learning is the focal point, but the ML model is only one component of the much larger enterprise analytic body, the Corpus AI. Moreover, the data scientists who build the ML models are often far removed from the people who distill and determine decisioning strategies, implement rules systems, or triage the decisions of the Corpus AI. To address this disconnect and truly operationalize AI, guardrails must be in place such that the overall Corpus AI continues to perform while components change. Rank distillation is one of the methods – read on to learn more about this important data science method.
Retraining ML Models: The Care and Feeding of AI Systems
All AI systems need to have their machine learning models updated, strategies adjusted and the effectiveness of rules systems assessed – how successfully are the decisioning system and methods meeting the business objective? Model retrains are one of the major components that effect change, since the ML models are the predictive and detection components of the Corpus AI, and directly drive other decision components downstream.
Naively executed, a retrained ML model will improve but may accentuate different behaviors compared to the prior model. This results in substantive changes in different customer behaviors moving between different model score bands – even if the overall model delivers better global prediction. The challenge becomes, then, that the strategy, methods and rules systems are tuned to the old model’s behaviors within a score band. How can this be rectified?
The Risks of Retraining
For example, perhaps the AI operator is satisfied with the detection of cross-border ATM fraud at a score threshold of 800, and with dollar-value rules that block transactions at $200 when both the score and dollar thresholds are met. In the new model, perhaps the same behavior now generates a score of 600; without modification, the rule would not capture the same volumes of this event, resulting in lower case volumes and less efficacy in overall fraud detection.
Since AI systems have hundreds, sometimes thousands of rules, impedance mismatches between the old and new models’ scoring of the same behaviors can add up to a highly performant model upgrade, but a poorly performing AI decisioning system – more bluntly, a “great model, but bad decisions.” As such, we need to be able to quantify the impact of a model retrain on the full Corpus of AI and minimize the behavior impedance mismatch.
Rank Distillation Smooths the Transition from Old Model to New
Fortunately, it is well known that there is not one model solution, but a huge number of solutions when we train models. The trick is how to select the solution that minimizes behavior impedance mismatches across the dataset, so rules continue to be effective. Figure 1 below represents this scenario in a schematic.
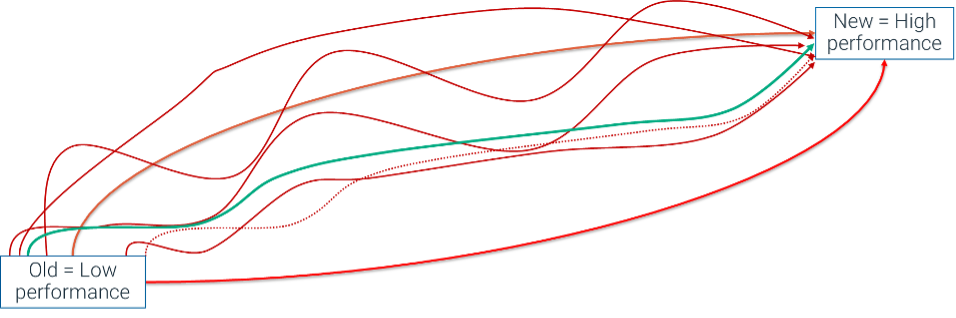
Fig. 1. There are many paths to achieve higher model performance.
Simply put, a customer should not have a significantly different score or AI decisioning system outcome because one of the multitude of solutions in Figure 1 is chosen over another. Similar behaviors should be expressed by both models. While the newer model has better detection capability, it needs to be constrained to understand that it, in fact, finds performance lift without completely disrupting the Corpus AI, and ultimately the realization of that value in decisioning.
The method FICO has used to achieve this is called score rank distillation. Rank distillation constrains the ML model to a solution that minimizes differences between old and new model scores for similar behaviors. The resulting new model then requires fewer adjustments in the downstream business decisioning strategies and rules of the Corpus AI.
A Student Model - Teacher Model Approach
Conventional supervised machine learning uses a loss function for model training that optimizes classification performance only on the new data, without any insight into the old model’s behaviors that it is intended to replace. In this rank distillation approach, the loss function penalizes large deviations in the new model’s predicted output compared to the old model’s prediction; simultaneously, it also optimizes detection performance of the new model on ground-truth target values. The old model is used as a teacher model and the newly trained model is the student model.
Given multiple, equally fit models, the one that minimizes disturbances to treatments of customers based on score difference between old teacher model and new student model is preferred. Figure 2 below shows the performance of the model trained using conventional loss function alongside another model trained using our novel loss function.
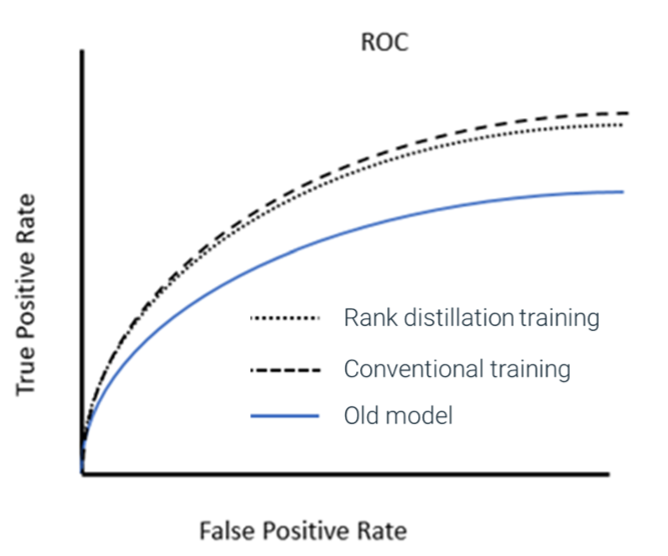
Fig. 2. Both the model trained using conventional loss function and the model trained with FICO’s ranked distillation provide similar lift in performance compared to the original model. Note: This figure shows only theoretic value; it does not measure the conventional training to be more misaligned with the rules/strategy of the existing Corpus AI, which ultimately lowers the decision performance metric.
Figure 2 shows an important myopic nuisance, although conventional training looks slightly superior to the rank distillation training. If the behaviors in high-scoring cases for the conventional model are significantly different than the old model, then the slight lift in the conventional training (above) is never achieved. In fact, overall decisioning system performance can dramatically fall below the rank distillation model due to the behavior impedance mismatch and its negative impact on the rest of the Corpus AI.
How Often Do New Models Deliver Less Performance?
New models can underperform alarmingly easily if you take your eyes off the Corpus AI. A dataset comparison of the top 1% of cases generated by the new conventional fraud model to the top 1% in the old fraud model showed that 150% more chip fallback cases were flagged in the new model. But with the rank distillation approach, the new model yielded a similar number of chip fallback transactions in the top 1% compared to the old model. (Figure 3)
Since the strategy and rules systems will not adjust to drastic swings in case numbers (without entire studies and an overhaul of strategy/rules), using the new conventionally trained model will result in a larger number of false positives, due to the Corpus AI making decisions based on interplay between model scores and decisioning rules. This can prevent realizing the new model’s value, or worse, result in a perhaps-lower overall decision performance of the Corpus AI due to the impedance mismatches.
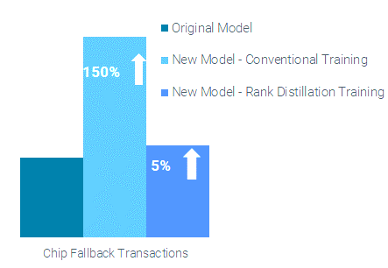
Fig. 3. Relative frequency of chip fallback transactions in the top 1% cases generated by original model, and the newly trained models using conventional and rank distillation approaches. The conventionally trained model produced 150% more chip fallback cases in the top 1% of cases but the rank distillation model produced only 5% more, resulting in more stable model behavior and less impact to the Corpus AI decisioning rules and outcomes.
Key Takeaways
Here are three key learnings that data scientists and business people can use to better operationalize AI decisioning systems:
- Rank distillation models choose model training that treats customers not too differently than in the old model. This results in less disruption than from unconstrained model updates that are not sensitive to the rest of the Corpus AI.
- Conventional training may at times look better on only model training data, but without a view to the entire Corpus AI, “better” may not be realized in value as established strategies, methods and rules change slowly or not at all.
- Machine learning models can be constrained to be good citizens in the Corpus AI by reflecting and prioritizing two benefits: minimal operational disruption and customers receiving correct outcomes when the model is used to distill appropriate actions in the overall Corpus AI system.
Keep up with my latest thoughts on data science and Responsible AI by following me on LinkedIn and Twitter @ScottZoldi.
Popular Posts

Average U.S. FICO® Score at 716, Indicating Improvement in Consumer Credit Behaviors Despite Pandemic
The FICO Score is a broad-based, independent standard measure of credit risk
Read more
The GSE Data Is Public. Here's What It Shows About Credit Score Modernization.
Independent Milliman analysis of GSE historical data confirms what anyone can now verify directly: FICO® Score 10T is the most predictive score.
Read more
FICO® Score High Achievers: Is Age the Only Factor?
<p>FICO’s latest research on <a href="http://www.fico.com/en/blogs/risk-compliance/us-credit-quality-rising-the-beat-goes-on/" target="_blank">national FICO® Score distribution</a> shows that US credit quality continues to trend upwards, with an increasing number of consumers scoring in the highest scores ranges. Given that, we decided it was time to refresh our study on “<a href="http://www.fico.com/en/blogs/risk-compliance/infographic-what-does-a-high-credit-scorer-look-like/" target="_blank">FICO® Score high achievers</a>,” where we examine the credit behavioural profiles of consumers with higher credit scores.</p> <p>As expected, our latest study showed that older people generally have higher scores, as has been the case in our <a href="http://www.fico.com/en/blogs/risk-compliance/age-before-beauty-credit-worthiness-before-youth/" target="_blank">past research</a>. This is largely because they have trade lines that have been open longer, which leads to higher scores (assuming the trade lines are in good standing and all other things equal). The most credit savvy among you will remember that length of credit history accounts for roughly 15% of the overall <a href="http://www.myfico.com/CreditEducation/WhatsInYourScore.aspx" target="_blank">FICO® Score calculation</a>.</p> <p>But for younger consumers, it isn’t too helpful to say, “just wait until you are 50 years old, and that will fix things!” Thus, I decided to dive deeper with our analysis, including looking at the credit behavioural characteristics of younger consumers with high FICO® Scores.</p> <p>In this analysis, I looked at credit characteristics for the two highest score bands, 750-799 and 800-850, which have about 16% and 23% of the population, respectively. I further broke this down by looking at the characteristics of the youngest 15% in each group, which occurs at age 29 for the 750-799 group and 43 for the 800-850. We used FICO<strong>®</strong> Score 9 for our analysis, and examined typical variables of the categories that go into the make-up of the score.</p> <p><a href="http://www.fico.com/en/blogs/wp-content/uploads/2016/10/FICO-Score-High-Achiever-table.png"><img class="alignnone size-full wp-image-29367" src="http://www.fico.com/en/blogs/wp-content/uploads/2016/10/FICO-Score-High-Achiever-table.png" alt="fico-score-high-achiever-table" width="715" height="747" /></a></p> <p>Since there’s a lot to dissect in this chart, I’ll highlight a few findings that struck me: <ul> <li><strong>Credit history.</strong> Higher scores are undoubtedly associated with a longer time on file. What’s striking is the higher average time on file for the 800+ group, both overall and for revolving accounts (the most common trade line). Clearly, it helps to start credit use early in life – but that’s not the sole determining factor for high scoring. The younger cohorts in both the 800+ and 750-799 groups have time on file medians significantly less than their older counterparts.</li> <li><strong>New credit.</strong> High credit scorers do, in fact, pursue new credit. We see little variation in months since last trade line opening and last inquiry among all groups observed.</li> <li><strong>Pay on time.</strong> As you might expect, the further in the past the delinquency, the higher the score – and that’s <u>if</u> a delinquency ever happened. 95% of the 800+ people and 72% of the 750-799 group have never been delinquent, which is a striking contrast to the 57% for the total population. The percentages for the younger groups are even higher, especially so for the 750-799ers. Collection items are also scarce for these high scorers. While 23% of the national population have collection items greater than $99, the figures are only 0.5% for the 800+ group and 3% for the 750-799 group. It is clear that, in conjunction with starting a credit file early, paying on time is a key trait of the FICO® Score high achiever.</li> <li><strong>Balance and utilization.</strong> Finally, we look at how credit is being used, focusing on revolving product use. (Since most people only have one mortgage or one auto loan, variation in instalment product figures is minimal and driven by payment history, which is near perfect for high scorers, as we’ve seen.) FICO® Score high achievers tend to have more open revolving accounts. While the % active trades and utilization are generally lower, by no means do high scorers avoid the use of credit products. What drives the difference here is the amount of <u>available</u> revolving credit utilized. The 800+ group is roughly 1/4 of the national median, both in total and on their highest utilized card; they also have lower balances and more cards<em>. </em>The 750-799 group is more active and higher utilized, but still only at 2/3 of the national figures. The young 750-799 group compensate with lower revolving balances and, as a result, lower utilization, which is in line with what we see for the 800+ group.</li> <li><strong>Benchmarks.</strong> I’d like to point out that while this study provides good benchmarks of the typical credit traits of the FICO® Score high achiever, individual credit profiles will vary widely. And keep in mind that when we sort groups of consumers as a whole by different behaviours, some results may look superficially odd. For example, the 800+ band has a longer median average open account time (128 months) than average revolving months on file (140 months).</li> </ul> So, what do we conclude? A huge takeaway is that high scorers don’t have too much in the way of serious delinquencies and negative public record data.</p> <p>In most respects, the young 800+ people are like their peer group. They really only differ markedly in their shorter credit history and higher non-mortgage balance, both of which are a function of life stage. Our results show that you don’t have to be a credit product hermit; these high scorers have more credit cards. The takeaway is to start credit activity early and maintain well-managed and moderate usage.</p> <p>In many ways, the young 750-799 people are more interesting because their age profile is much younger. Their credit characteristics differ more from their peer group, particularly in terms of length of credit history. They compensate by having almost pristine credit records and lower balances.</p> <p>Ultimately, 39% of US consumers are FICO® Score high achievers, which they accomplish by following common-sense credit practices. It ain’t rocket science!</p>
Read moreTake the next step
Connect with FICO for answers to all your product and solution questions. Interested in becoming a business partner? Contact us to learn more. We look forward to hearing from you.